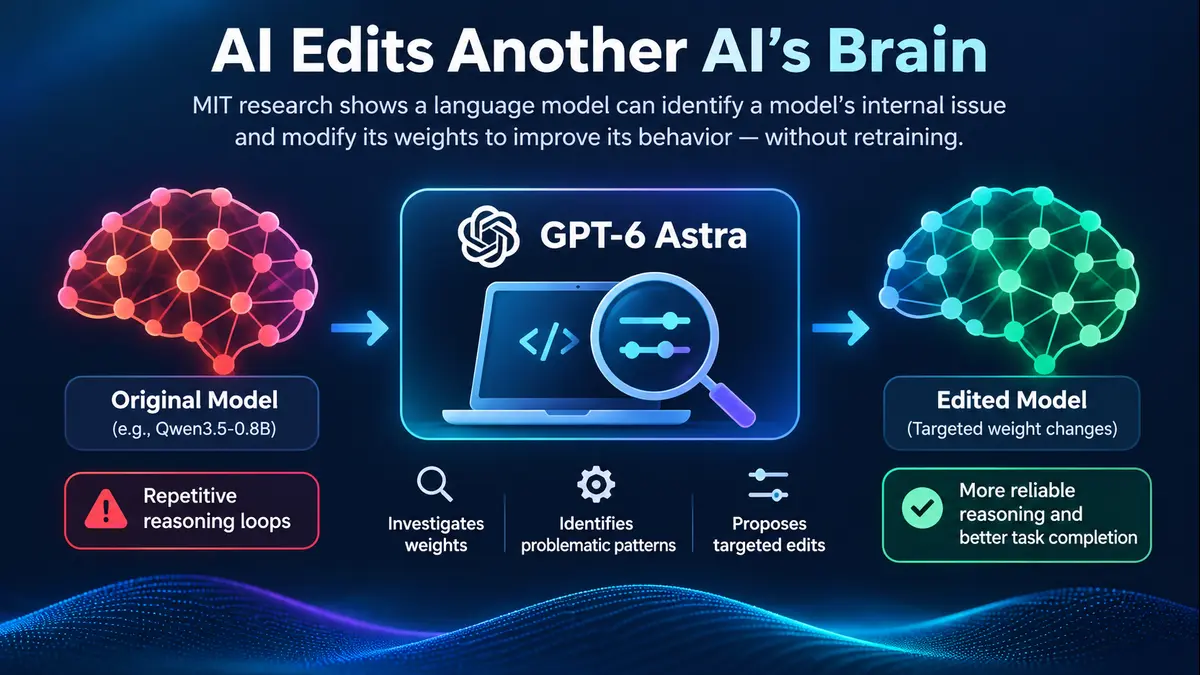
MIT researchers demonstrated how GPT-6 Astra modified a small portion of Qwen’s neural network weights to correct repetitive reasoning. This technical analysis examines the mathematical intervention, benchmark improvements, and limitations of weight-space programming.
MIT researchers used GPT-6 Astra to identify and modify a small portion of another AI model’s neural network weights. The experiment offers an early demonstration of targeted model repair without conventional retraining, but the results require careful interpretation.
A neural network can fail at a task even when it has learned much of what is needed to complete it. In some cases, the problem lies in how the model processes information rather than what it knows.
Researchers at the Massachusetts Institute of Technology (MIT) explored this scenario through weight-space programming, an experimental approach that uses a large language model to examine and modify another network’s numerical parameters.
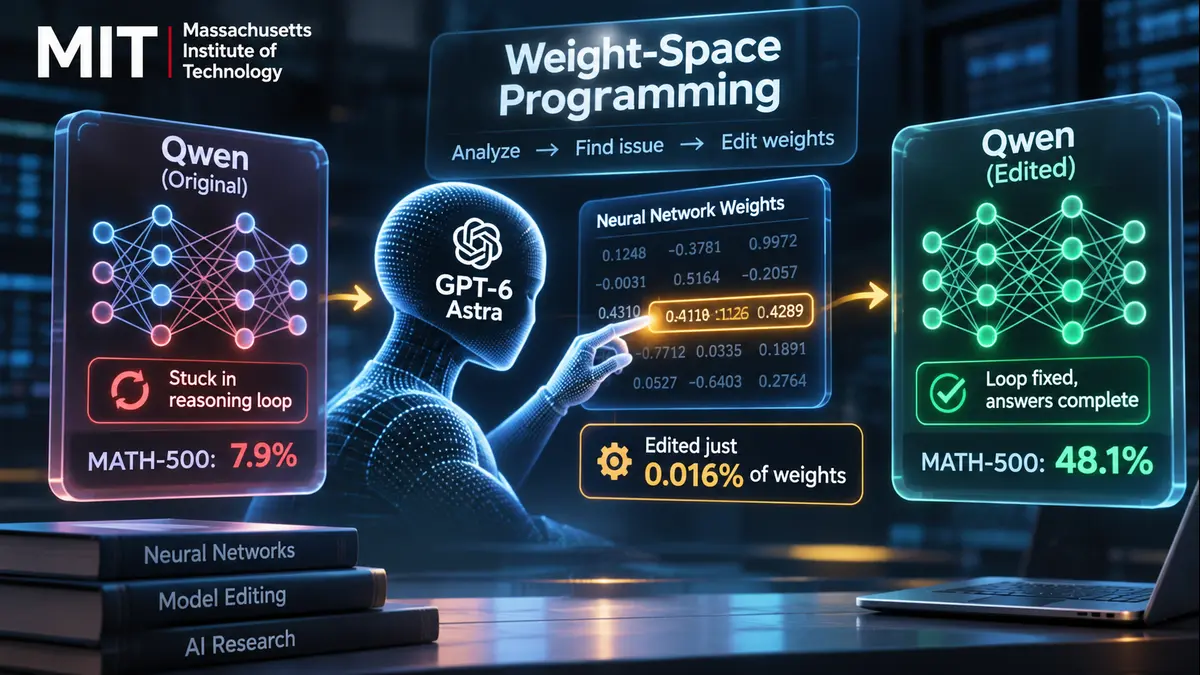
In a research post published on November 2, 2026, MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) demonstrated how GPT-6 Astra modified selected weights in Qwen3.5-0.8B, a small language model developed by Alibaba’s Qwen team. The intervention substantially reduced repetitive reasoning and improved benchmark performance without conventional retraining, while potentially reducing inference latency and computational costs by limiting unnecessary token generation.
To understand the significance of this research, it is important to look at how the researchers identified and modified specific weights within the neural network, and how those changes affected the model’s performance. Importantly, the experiment raises an interesting question: did the modification actually improve the model’s ability to reason and solve mathematical problems, or did it simply remove a repetitive behavior that was preventing the model from completing answers it was already capable of producing?
Weight-Space Programming vs. Gradient Descent
Neural networks learn by adjusting numerical values known as weights, which determine how information is processed and how strongly different signals influence the model’s output. During conventional training, the model is given examples and produces predictions, which are then compared with the expected results. The difference between the prediction and the correct answer is measured using a mathematical function called the loss function. An optimization algorithm then uses this information to adjust the weights, gradually reducing errors and improving the model’s performance through repeated training cycles.
A simplified gradient-descent update is:
W(new) = W(old) − η × ∇L(W)
Here, W represents the model’s weights, η is the learning rate that controls the size of each adjustment, and ∇L(W) is the gradient of the loss function, which indicates how the weights should change to reduce errors.
Optimization algorithms such as Adam use these gradients, along with additional mathematical calculations, to update the model’s parameters during training. These algorithms can efficiently optimize neural networks containing billions of parameters, but they do not explicitly identify which internal components are responsible for particular behaviors or failures.
Weight-space programming takes a different approach. Instead of relying on gradients to determine parameter updates, a general-purpose AI model examines another neural network’s architecture, numerical weights, and observed behavior. It then investigates which parts of the network may be contributing to a specific problem and proposes targeted modifications to those parameters.
Researchers have previously developed methods for modifying specific behaviors or learned associations within neural networks, so direct model editing is not entirely new. What makes the MIT experiment particularly interesting is that GPT-6 Astra performed the investigation and proposed the modifications itself, using its reasoning capabilities and computational tools rather than a conventional gradient-based training process.
The Qwen Experiment: Identifying a Reasoning Failure
The researchers conducted their experiment using Qwen3.5-0.8B, a small language model developed by Alibaba’s Qwen team, containing approximately 800 million parameters.
The model had a known limitation in its thinking mode, where it could become trapped in repetitive reasoning loops. Instead of progressing toward a solution, it would repeatedly revisit similar calculations or explanations, sometimes generating thousands of tokens without producing a final answer. This behavior affected its performance on mathematical reasoning tasks.
To investigate the problem, the researchers provided GPT-6 Astra with access to Qwen’s neural network weights through a Python environment, along with practice questions from the training portions of the GSM8K and MATH datasets. These datasets contain mathematical problems used to evaluate language models’ reasoning and problem-solving abilities.
Astra could inspect the model’s numerical parameters, perform calculations, and run controlled tests to observe how Qwen responded to different questions. These tests involved forward passes, in which inputs are processed through a neural network to generate predictions without changing its weights.
The researchers conducted separate experiments allowing Astra 10, 25, or 50 forward passes, with each pass capable of evaluating multiple examples. Astra was not permitted to use conventional training loops or gradient-based optimization, and it had no access to the final benchmark questions used to measure the improvements.
By examining how Qwen behaved during successful and repetitive responses, Astra investigated which internal computations might be contributing to the problem. Its analysis identified a candidate numerical direction associated with the repetitive behavior, particularly involving the multilayer perceptron (MLP) components in layers 15 and 19 of the network.
These findings guided the researchers’ subsequent experiments in modifying selected weights within those layers to reduce the unwanted reasoning loops.
How AI Edited Qwen’s MLP Weights
Qwen3.5-0.8B contains 24 language-model layers that process information through a series of mathematical operations. Each layer includes a component known as a multilayer perceptron (MLP), which helps transform the information passed through the network.
An MLP uses numerical parameters arranged in matrices to process and modify the model’s internal representations. One important component is the output matrix, also called the down-projection matrix, which determines how the processed information contributes to the next stage of the network.
In simplified mathematical form, this operation can be represented as:
Output = W(down) × f(Input)
Here, W(down) represents the output weight matrix, while f(Input) represents the intermediate computations performed by the MLP. Qwen uses a more complex architecture involving gated operations, but the simplified equation illustrates how the output matrix transforms information.
The columns of this matrix contain numerical values that determine how individual intermediate activations contribute to the model’s internal representation. Changes to these values can therefore influence how the network processes information and generates responses.
During the experiment, GPT-6 Astra identified a candidate numerical direction associated with Qwen’s repetitive reasoning behavior. Its analysis suggested that certain columns within the MLP output matrices of layers 15 and 19 were contributing to this behavior.
Rather than modifying the entire network or disabling these layers, Astra proposed targeted adjustments to selected columns within their output matrices.
The final intervention targeted 64 output columns in each of the two layers. Since Qwen has a hidden dimension of 1,024, the total number of parameter positions involved was calculated as:
64 × 1,024 × 2 = 131,072 parameter positions
This represented approximately 0.016% of the model’s weights, based on its rounded parameter count of 800 million.
An independent analysis of the edited model’s checkpoint subsequently reported that 130,188 parameter values actually differed from the original model. The small difference between the targeted and changed parameter counts arose from numerical rounding.
The audit also found that Astra’s final modification went beyond simply removing the identified numerical direction. The operation subtracted six times the selected directional projection, applying a stronger adjustment intended to suppress its influence on the model’s reasoning.
The experiment therefore involved changing specific numerical contributions within two layers, rather than replacing or disabling major parts of the neural network. By adjusting a small fraction of its parameters, Astra was able to alter Qwen’s tendency to enter repetitive reasoning loops while leaving the overwhelming majority of its weights unchanged.
How Astra Tested and Validated the Edits
The researchers did not arrive at the final modification in a single attempt. The published experimental logs show that GPT-6 Astra examined several possible changes, tested their effects on Qwen’s responses, and revised its approach based on the results.
Astra initially investigated individual neurons before exploring modifications across the identified layers. It also tested changes along a randomly selected numerical direction of comparable magnitude to determine whether the improvement was specific to the identified repetition-related pattern.
The most substantial improvement came from the experiment that allowed Astra 50 forward passes to investigate the model and evaluate potential modifications.
The researchers measured performance using several established AI benchmarks. MATH-500 evaluates mathematical problem-solving, GSM8K tests reasoning on grade-school mathematics questions, and IFEval measures how reliably a language model follows instructions.
The reported results were as follows:
| Evaluation measure | Original model | Edited model |
|---|---|---|
| MATH-500 accuracy | 7.9% | 48.1% |
| GSM8K accuracy | 13.8% | 67.1% |
| IFEval score | 21.0% | 62.3% |
| MATH-500 responses reaching token limit | 93.0% | 33.1% |
The evaluations were conducted with Qwen’s thinking mode enabled, specified sampling settings, and a maximum output length of 32,768 tokens per response.
The results indicate that the edited model was considerably more successful at completing mathematical problems and following instructions under the researchers’ testing conditions.
However, the experiments using 10, 25, and 50 forward passes produced different weight modifications. They should not be interpreted as evidence that simply increasing the number of forward passes would consistently produce better results.
The researchers also released the modified Qwen model publicly. A separate evaluation of the edited checkpoint reported 51.0% accuracy on MATH-500, broadly supporting the improvement observed in the original experiment.
Why the Benchmark Improvement Needs Context
Although Qwen’s mathematical performance improved substantially, the results reveal something important about the nature of the model’s original problem.
Before the modification, 93% of its MATH-500 responses reached the maximum permitted output length of 32,768 tokens. In many cases, the model continued generating repetitive reasoning without arriving at a final answer.
After Astra modified the selected weights, the proportion of responses reaching that limit fell to 33.1%.
An analysis of the released experimental outputs, covering 1,152 practice problems, found that 579 previously unsuccessful responses became successful after the modification. Of those, 576 had originally been cut off at the output limit.
The findings suggest that much of the improvement came from reducing repetitive reasoning and allowing Qwen to complete solutions it was already capable of producing, rather than teaching the model entirely new mathematical abilities.
Reducing unnecessary token generation could also lower inference latency and computational costs, since shorter responses generally require less processing. However, the experiment did not establish a quantified reduction in response time.
The evaluation settings are equally important when interpreting the reported improvement.
Qwen’s official documentation acknowledges the model’s tendency to enter repetitive reasoning loops and recommends allowing up to 81,920 output tokens for complex mathematical and programming benchmarks. The MIT experiment used a lower limit of 32,768 tokens.
An independent technical audit also found that the original, unmodified model achieved different baseline results when evaluated using alternative inference settings, including those recommended by Qwen’s developers.
The increase from 7.9% to 48.1% therefore reflects a substantial improvement under the researchers’ specific evaluation conditions, rather than a universally established increase in the model’s mathematical reasoning ability.
The experiment demonstrates that targeted modifications to neural network weights can correct certain behavioral failures without conventional retraining. Whether similar interventions can reliably improve models with different architectures or more complex reasoning weaknesses remains an open research question.
What the Follow-Up Research Reveals
The MIT researchers also investigated whether weight-space programming could improve Gemma 3 270M, a smaller language model developed by Google that rarely experienced the repetitive reasoning loops observed in Qwen.
Unlike Qwen, Gemma’s mathematical failures mainly involved incorrect calculations, flawed reasoning, and invalid algebraic steps. GPT-6 Astra examined the model and attempted targeted weight modifications, but the changes produced no meaningful improvement in mathematical performance. The experiment suggested that correcting an existing behavioral problem may be easier than introducing reasoning abilities a model has not adequately learned.
Further research explored how reliably weight-space programming works across different models and tasks.
A study published on November 6, 2026 examined 16 weight-editing experiments involving Qwen3.5 models of different sizes. Some targeted modifications produced substantial improvements on mathematical reasoning, instruction-following, and scientific benchmarks. However, results varied across experiments, and improvements in one task did not consistently extend to others. In six experiments, the original weights were retained because the proposed changes could not be reliably validated.
Another study published on November 5, 2026 examined whether language models genuinely understand the neural network weights they analyze. Using a different AI model and smaller image-classification networks, the researcher found that the system could perform certain numerical calculations accurately but sometimes relied on familiar dataset patterns when interpreting what the network had learned.
Both follow-up studies are preliminary preprints, and their findings do not directly overturn MIT’s results. They do, however, highlight important challenges in understanding neural network behavior, identifying effective parameter modifications, and ensuring that improvements remain reliable across different tasks and models.
Implications for AI Model Engineering
Weight-space programming could introduce a new approach to diagnosing and correcting problems in neural networks, particularly when a model’s performance is affected by specific internal behaviors rather than a lack of learned capabilities.
In conventional AI development, engineers typically address such problems through prompt adjustments, changes to inference settings, fine-tuning, or additional training. The MIT experiment suggests that another option may eventually become available: using an advanced AI model to investigate the underlying numerical parameters and identify targeted modifications that correct a particular failure.
For example, future AI engineering systems could continuously monitor model behavior, identify recurring errors, examine the relevant neural network components, and propose adjustments to selected weights. Each modification would need to undergo controlled testing to determine whether it resolves the original problem without affecting performance elsewhere.
Potential applications include improving model reliability, reducing unnecessary token generation, and lowering inference costs where targeted edits can eliminate repetitive or unproductive reasoning. Such benefits would depend on whether the modifications remain effective across different tasks and operating conditions.
There are also significant engineering challenges. Even a small change to a model’s weights can alter behaviors that were not part of the original investigation. Deploying these modifications in production environments would require extensive regression testing, safety evaluations, version control, and mechanisms to restore earlier model checkpoints if unexpected problems arise.
The MIT experiment demonstrates that a general-purpose AI model can, under certain conditions, investigate another neural network’s internal behavior and make targeted parameter changes without conventional retraining. It does not establish that AI systems can independently acquire new capabilities through weight editing or reliably improve arbitrary models.
For AI researchers and engineers, the next challenge is to determine whether such interventions can be reproduced consistently, applied to larger and more complex models, and validated without introducing new failures. The computational cost of investigating and testing candidate edits must also be compared with established approaches such as fine-tuning.
Weight-space programming remains an experimental technique, but the research opens another avenue for understanding and maintaining neural networks. Its long-term value will depend on whether targeted model repairs can become reliable, measurable, and economical enough for practical AI development.
Discover more from Poniak Times
Subscribe to get the latest posts sent to your email.